

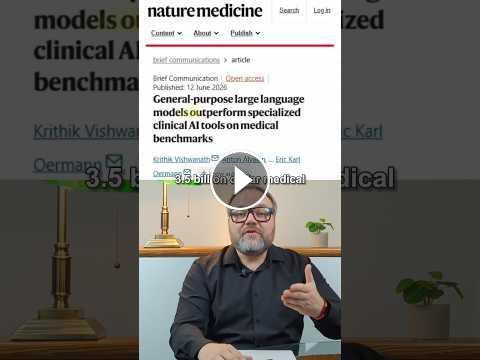
NYU tested specialized medical AI tools like OpenEvidence and UpToDate against general AI models such as GPT, Claude, and Gemini using real doctor queries. Despite costing billions and being widely used in hospitals, these specialized tools were outperformed on every question by the general AI models according to blind evaluations by medical professionals. The study reveals that traditional medical AI relies on retrieval-augmented generation (RAG), pulling information from medical databases, which can introduce errors and reduce answer quality. In contrast, frontier AI models integrate knowledge directly into their training, resulting in more accurate and reliable responses. This challenges the common assumption that domain-specific AI tools automatically provide better support for medical decisions. With AI tools now influencing patient care, this research underscores the necessity of independent, rigorous testing rather than relying on marketing claims. It also highlights the potential for advanced general AI to disrupt specialized healthcare solutions, urging hospitals and practitioners to reconsider their AI tool choices carefully. #OpenEvidence #UpToDate #NYUAIStudy #MedicalAI #ChatGPT #ClaudeAI #GeminiAI #HealthcareInnovation #RetrievalAugmentedGeneration #AIEvaluation #MedicalTechnology #AIinHealthcare #AIDecisionSupport #HealthTech #ArtificialIntelligence
- Категория
- AI инструменты
Комментариев нет.
Следующее
Auto
-
11:25

The Introvert Homebody | Productive Medical Billing WFH Day | Cleaning, Lunch Break & Ross Finds
-
00:18
Study smarter, not harder with these techniques + AI tools ⚡ #studytips #study #futurecoded
-
11:27
I write about everything as a medical writer! Cynthia Daoud's first 3 years as a medical writer
-
04:35
ECHS Jalandhar Cantt Recruitment 2026 | Medical, Paramedical & Non-Medical Posts | Qualification
-
1:25:08
Airforce Medical Assistant GK GS-03 Official Paper |Airforce Y Group & Medical Offical Paper 02/2027
-
00:36
Study finds remote work may be hurting job prospects for new graduates
-
52:21
Airforce Medical Assistant Computer Class-03|Airforce Y Group & Medical Offical Paper 02/2027
-
00:54
Top 5 AI tools for students 2026 | Best AI - Study, Notes & Exams
-
52:21
Airforce Medical Assistant Computer Class-03|Airforce Y Group & Medical Offical Paper 02/2027
-
52:01
Airforce Medical Assistant GK GS-04 Official Paper |Airforce Y Group & Medical Offical Paper 02/2027
-
00:21
Сайты для заработка | Заработок в интернете 2023
-
10:03
Пассивный доход в 2024 с минимальным риском [Инструкция для новичков]
-
06:33
Где найти подработку ЗА ОДИН ВЕЧЕР? Работа онлайн в 2024
-
00:54
Как новичку начать зарабатывать на трейдинге в 2024 году?
-
11:05
Как ЗАРАБОТАТЬ ШКОЛЬНИКУ в ИНТЕРНЕТЕ ? Самые Лёгкие Способы заработка денег в интернете 2024 !
-
13:39
Как зарабатывать с ТЕЛЕФОНА в 2024 году? Лучший, проверенный способ
-
34:57
Лучший интернет-бизнес для старта в 2024. (Для новичков)
-
01:00
Как майнить криптовалюту с телефона?Мобильный майнинг! 3$ за регистрацию!Заработок в интернете !
-
12:28
ФРИЛАНС с НУЛЯ в 2024 году| РЕАЛЬНО ли ЗАРАБОТАТЬ?
-
05:59
Как заработать на Pinterest? Бесплатный Трафик о котором никто не говорит.
 Загрузка...